What Kurtosis Reveals About Analytical Data
A residual plot can look acceptably random while a small number of extreme errors quietly dominate its statistical behavior. Kurtosis makes those tail events visible in a single diagnostic measure. For scientists fitting chromatograms, spectra, mass-spectrometry signals, or calibration data, that distinction matters: heavy-tailed residuals can indicate unresolved structure, baseline failure, detector artifacts, or an unsuitable error model even when the fitted curve appears convincing.
What kurtosis measures
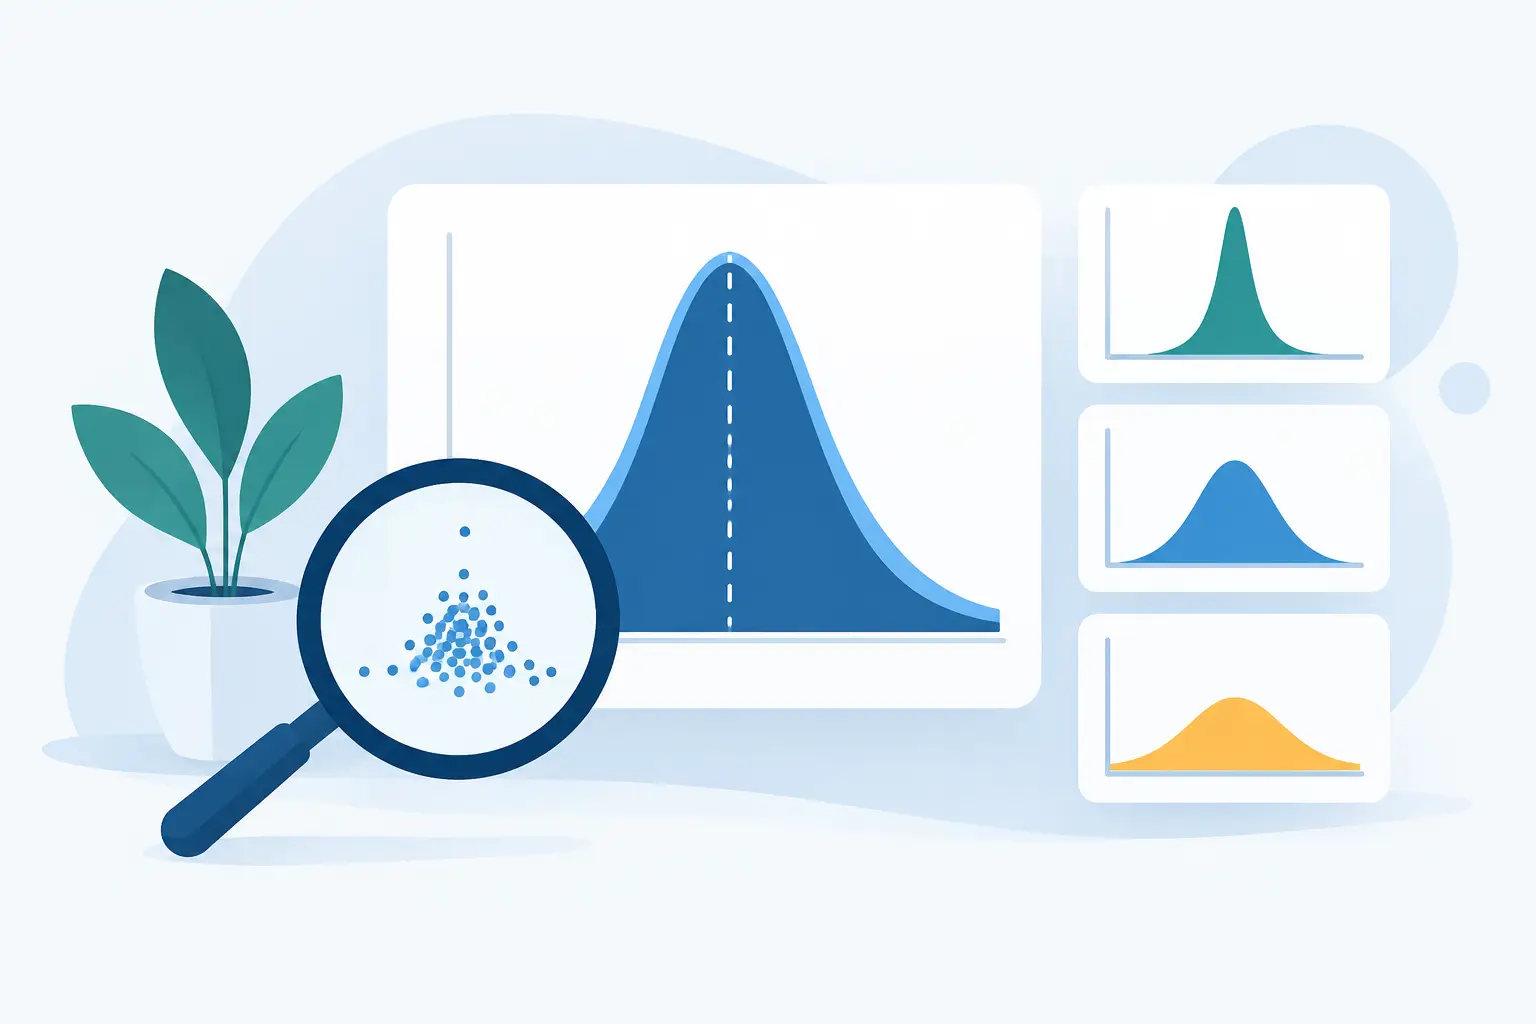
Kurtosis describes the tail behavior of a distribution relative to a normal distribution. It is often described as a measure of “peakedness,” but that shorthand is incomplete and can be misleading. In practical analytical work, kurtosis is most useful for asking a more specific question: how often do observations fall far from the distribution’s center?
The population statistic is commonly written as:
[ text{Kurtosis} = frac{E[(X – mu)^4]}{sigma^4} ]
Because deviations are raised to the fourth power, large deviations receive disproportionate weight. A handful of serious outliers can therefore change kurtosis substantially, even when the mean and standard deviation move only modestly.
A normal distribution has a Pearson kurtosis of 3. Many software environments instead report excess kurtosis, defined as Pearson kurtosis minus 3. Under that convention, a normal distribution has an expected excess kurtosis of 0. This reporting difference is not cosmetic. A reported value of 0 may represent normal-like tails in one program, while another program would report 3 for the same data. Any technical report should state the convention used.
Interpreting positive and negative values
Positive excess kurtosis indicates heavier tails than a normal distribution. The data may contain more extreme observations, more frequently, than Gaussian assumptions predict. Negative excess kurtosis indicates lighter tails and, often, a more bounded distribution.
Neither result is automatically good or bad. A negative value may reflect a stable, bounded process, but it can also arise from truncation, aggressive filtering, or a limited measurement range. Positive kurtosis may expose a genuine intermittent process, but it may also reveal data-quality problems that should not be absorbed into the model.
Why kurtosis matters in fitted analytical data
In curve fitting, the question is rarely whether the raw signal is normally distributed. Chromatographic and spectroscopic signals contain peaks, baseline structure, noise, and sometimes real low-level features. Their raw value distribution is shaped by the experiment and is not, by itself, a clean measure of model adequacy.
The more informative target is usually the residual distribution: observed signal minus fitted signal. If a model, baseline, weighting scheme, and noise assumption are appropriate, residuals should be structure-free and consistent with the expected measurement error. Kurtosis helps test whether rare but large residuals are undermining that expectation.
Consider a peak-fitting result with small residuals across most of the trace but several large deviations near a shoulder, tail, or inflection point. The overall R-squared may still be high because the dominant peak explains most signal variation. High residual kurtosis, however, signals that the remaining error is not ordinary random variation. In this setting, likely causes include an omitted component, an incorrect peak shape, an inadequate baseline function, saturation, or an unmodeled instrumental event.
This is why visually plausible fits are insufficient for research-grade interpretation. A model should be assessed not only by how closely it follows the signal, but also by whether its residuals support the statistical assumptions used to estimate uncertainty and defend parameters.
Kurtosis is a diagnostic, not a verdict
A single kurtosis value cannot identify the source of a problem. It should be interpreted with residual plots, leverage and influence diagnostics, signal-domain knowledge, and the acquisition history. Most importantly, it should be evaluated at the locations where extreme residuals occur.
For example, high kurtosis concentrated at the beginning or end of a chromatographic run may point to baseline drift, injection artifacts, or integration-window issues. Extreme residuals occurring only at the apex of a strong peak may indicate detector nonlinearity, digitization limits, or inappropriate weighting. In a mass spectrum, isolated high residuals can result from unmodeled ions, incorrect isotope-pattern assumptions, or thresholding artifacts.
The response is not to delete observations simply because they raise kurtosis. Removing difficult data without a documented physical or instrumental reason can make a model look statistically cleaner while making it less truthful. Instead, inspect the measurement, determine whether the point is valid, and then revise the model or preprocessing method only when the evidence supports it.
Sample size and estimator choice affect the result
Kurtosis is intrinsically sensitive to sample size. In a short dataset, one extreme observation can dominate the calculation. Small-sample estimates may also be biased, depending on the formula used by the software. Comparing values across methods is meaningful only when the same estimator, treatment of missing data, and preprocessing rules are used.
This sensitivity has practical consequences for narrow fitting windows. A local fit with 20 to 40 points can produce a volatile kurtosis estimate, particularly when parameters are highly correlated or the fit includes a sharp feature. The statistic should be treated as evidence to investigate, not as a rigid pass-fail threshold.
For larger high-throughput datasets, kurtosis becomes more stable but can become extremely sensitive to small departures from normality. A very large residual set may yield a statistically detectable non-normal tail behavior that has little practical effect on parameter estimates. Scientists should distinguish statistical significance from analytical significance: does the behavior alter peak area, peak position, component resolution, uncertainty, or a process decision?
How to use kurtosis in a defensible fitting workflow
Kurtosis has the greatest value when it is embedded in a structured residual-analysis workflow. Begin with a fit that incorporates the appropriate baseline and physically justified peak or signal model. Then inspect residuals as a function of the independent variable before calculating distributional summaries. Patterns, oscillation, localized excursions, and variance changes are often more revealing than a scalar statistic.
Next, calculate residual kurtosis using a clearly identified convention. Pair it with the residual mean, standard deviation, skewness, and a normal probability plot. Skewness answers whether errors are asymmetric; kurtosis answers whether their tails are unusually influential. Together, they provide a more complete view than either statistic alone.
If kurtosis is high, investigate competing explanations systematically. Check whether baseline correction leaves broad curvature. Test whether adding a chemically or physically plausible component removes localized residual structure. Evaluate alternate line shapes only when they are defensible for the instrument and analyte. Examine whether residual variance rises with signal intensity, which may call for weighted fitting rather than a different peak model.
A weighted least-squares approach can be especially relevant when measurement variance is signal-dependent. Without weighting, high-intensity regions may dominate the objective function and leave the low-signal region with disproportionately large residuals. That can inflate tail diagnostics while obscuring weak but consequential components. Weighting is not a cure for incorrect model structure, but it aligns the fitting criterion with the measurement-error behavior.
Common mistakes when reporting kurtosis
The first mistake is failing to say whether the result is Pearson or excess kurtosis. The second is reporting the statistic for raw signals as proof of fit quality. The third is treating a near-zero excess value as evidence that the model is correct. A normal-looking residual distribution can still retain clear serial structure, baseline bias, or a physically implausible parameter set.
Another frequent error is using normality thresholds mechanically. There is no universal kurtosis cutoff that certifies an analytical model. The acceptable degree of tail behavior depends on the data volume, noise mechanism, fitting objective, regulatory context, and consequence of parameter error. For a screening workflow, modest tail departures may be tolerable. For a quantitative assay, publication, or regulated decision, they warrant explicit examination and documentation.
Scientific fitting software should therefore make residual diagnostics reproducible rather than leaving them as visual afterthoughts. In platforms such as PeakLab, integrated baseline-and-peak modeling, constrained nonlinear fitting, and statistical reporting support a workflow in which anomalous tails can be traced back to model structure and measurement behavior rather than hidden behind a favorable visual overlay.
The useful question is not whether kurtosis is high or low in isolation. It is whether the tails reveal errors that could change the scientific claim. When that question guides the analysis, kurtosis becomes a practical safeguard against accepting a fit that looks polished but cannot withstand technical scrutiny.