Second-Derivative Analysis for Peak Resolution
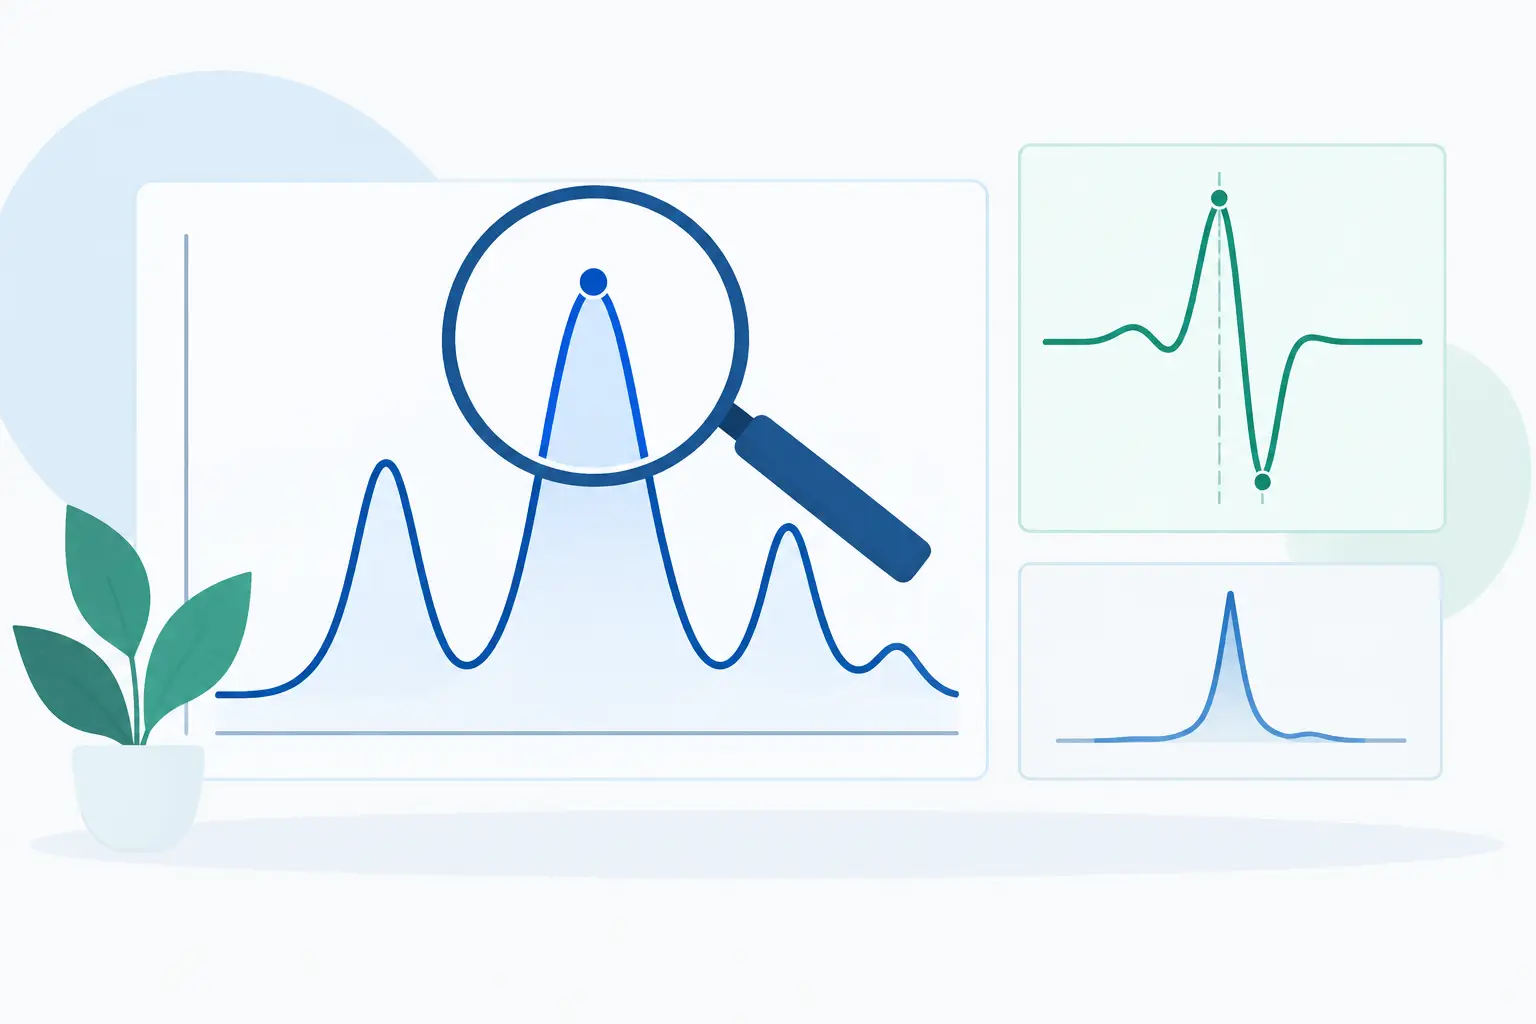
A shoulder at 1652 cm⁻¹, a partially merged chromatographic band, or a broad XPS envelope can contain information that a conventional plot does not visibly resolve. Second-derivative analysis is often used to expose that structure. It can reveal peak positions obscured by overlap, reduce the visual dominance of broad backgrounds, and distinguish features that appear to be one peak in the raw signal.
Those advantages do not make a derivative trace a fitted model. Derivatives amplify noise, react strongly to sampling density and smoothing choices, and can create apparent features that have no physical basis. For research-grade interpretation, second derivatives are most valuable as a diagnostic and initialization tool within a controlled baseline-correction, peak-fitting, and statistical-validation workflow.
What second-derivative analysis measures
The first derivative describes the rate of signal change with respect to the measured variable, such as wavelength, wavenumber, retention time, mass-to-charge ratio, or temperature. The second derivative describes how rapidly that slope changes. In mathematical form, for a signal (y) measured as a function of (x), the second derivative is (d²y/dx²).
For an isolated, symmetrical absorption-like peak, the second derivative commonly produces a negative minimum near the original peak center. The broad peak seen in the original signal is transformed into a narrower derivative feature, making neighboring centers easier to distinguish. A broad, slowly changing baseline contributes less strongly than a narrow peak, which is one reason derivatives can make hidden structure more apparent.
The interpretation depends on signal convention. Peaks plotted upward, downward, or after a transformation will not necessarily have the same derivative sign. Analysts should therefore confirm the relationship between derivative extrema and original-signal peak centers for the specific instrument, preprocessing sequence, and data type rather than treating every negative minimum as a chemical component.
Where second-derivative analysis is most useful
Derivative processing is particularly effective when the analytical question is positional: Are there multiple components in a broad envelope? Where should candidate peak centers be initialized? Does a spectrum contain a weak shoulder that warrants further modeling?
In IR, Raman, UV-Vis, and NIR spectroscopy, second derivatives can separate closely spaced vibrational or electronic bands that merge in the measured spectrum. In chromatography, they can help locate likely component maxima within unresolved or partially resolved peaks. In XPS and other surface-analysis workflows, derivatives may help identify structure within broad envelopes before constrained component fitting begins.
The method is less decisive when the goal is accurate quantitation. Derivative amplitudes are not directly equivalent to original peak areas, and their magnitude depends on peak width, filtering, and numerical differentiation settings. A derivative trace may indicate that two components are plausible; it does not establish their areas, widths, shapes, concentrations, or chemical assignments.
Why derivatives can mislead
Differentiation magnifies high-frequency variation. Random detector noise that is barely visible in the original trace can become a sequence of alternating maxima and minima after second differentiation. A noisy derivative can suggest multiple narrow peaks where the underlying data supports only one broad feature.
This is not merely a cosmetic problem. Overcalling derivative minima can lead to overparameterized fits, unstable peak areas, and models that appear persuasive on a graph but fail residual analysis or produce nonphysical parameters. The risk increases when signal-to-noise is low, data are undersampled, or aggressive smoothing is used to make the derivative look cleaner.
Smoothing introduces its own trade-off. Too little smoothing leaves noise-dominated derivatives. Too much smoothing broadens or shifts narrow features, suppresses weak components, and can merge the very peaks the derivative was intended to reveal. Savitzky-Golay filtering is widely used because it can calculate smoothed derivatives from a local polynomial fit, but its window width and polynomial order must be selected in relation to the expected peak widths and the acquisition interval.
A defensible choice is not the setting that produces the largest number of apparent peaks. It is the setting that preserves reproducible features across sensible parameter changes and agrees with the original data, known instrument resolution, and relevant chemical or physical constraints.
A disciplined workflow for derivative-assisted fitting
Second-derivative analysis works best after the data have been inspected in their original form. Confirm the x-axis calibration, remove obvious acquisition artifacts when justified, and identify regions where detector saturation, discontinuities, or poor signal quality make interpretation unreliable. Resampling should be approached carefully because interpolation changes the numerical behavior of derivatives.
Baseline treatment comes next. Derivatives can reduce the visual influence of slowly varying backgrounds, but they do not eliminate the need to model baseline behavior when peak areas, component intensities, or residuals matter. A sloping chromatographic baseline, fluorescence background, scattering contribution, or XPS background can alter the apparent peak shape and change the derivative response near overlap regions.
After calculating a derivative with documented settings, use the resulting extrema as candidate locations, not fixed truths. Candidate centers should be tested by fitting the original signal with an appropriate peak-shape model and a baseline model suited to the measurement. Gaussian, Lorentzian, Voigt, exponentially modified Gaussian, asymmetric, and domain-specific line shapes answer different physical and instrumental requirements. Selecting one solely because it follows a derivative feature is not adequate.
At this stage, constraints matter. Peak centers may be bounded by spectral knowledge, expected retention behavior, isotope patterns, known line separations, or physically reasonable width ranges. Shared widths, fixed ratios, or linked positions may be appropriate when supported by the chemistry and acquisition method. Constraints should reduce ambiguity without forcing a preferred interpretation onto the data.
Finally, validate the model against the original data. Examine residuals for structured departures, assess parameter uncertainty and correlation, compare alternative component counts, and determine whether added peaks materially improve the model rather than merely reduce visual error. A valid model should provide stable parameters under reasonable changes to starting estimates and derivative settings.
Distinguishing peak detection from peak confirmation
The central analytical distinction is simple: second derivatives detect candidate structure; nonlinear modeling confirms whether that structure is supported. Treating these steps as interchangeable is a common source of false resolution.
Consider a broad chromatographic feature with two negative derivative minima. The result may indicate two coeluting analytes, but it could also reflect noise, a changing baseline, an asymmetric single peak, or a filtering artifact. Fit one-component and two-component models to the original signal, use chemically appropriate shape assumptions, inspect the residual patterns, and compare parameter stability. If the two-component solution produces highly correlated areas or implausible widths, the claimed separation is not defensible.
The same discipline applies to spectroscopy. A derivative shoulder can be an excellent prompt to investigate a hidden band, particularly when prior knowledge predicts an overlapping transition. It becomes credible evidence only when the original spectrum supports a constrained model with meaningful parameter estimates and acceptable residual behavior.
Software requirements for reproducible derivative work
Generic plotting packages can calculate numerical derivatives, but research workflows require more than a derivative command. The analysis environment should retain the original data, preprocessing decisions, smoothing parameters, baseline model, candidate peaks, fit constraints, model selection, and statistical outputs in a traceable record.
This is where integrated analytical modeling has a practical advantage. In R²N Software workflows, derivative-based peak detection can inform baseline-and-peak modeling rather than becoming an isolated visual operation. The objective is not simply to expose more extrema. It is to convert instrument data into statistically reliable, interpretable parameters that can withstand publication review, method development decisions, and internal technical scrutiny.
Second derivatives are powerful precisely because they are sensitive. That sensitivity should be used to formulate better questions of the data, then answered with constrained fitting and validation on the original signal. When derivative features, physical expectations, and residual-tested models agree, the resulting peak interpretation is far more than a visually attractive decomposition.