Haarhoff-van der Linde (HVL) Peak Fitting
A chromatographic peak can look acceptably Gaussian while still producing a biased area, retention estimate, or resolution calculation. That distinction matters when peaks overlap, tail into neighboring compounds, or sit on a changing baseline. The haarhoff-van der linde (hvl) function gives analytical scientists a physically informed way to represent asymmetric chromatographic peak shapes without treating asymmetry as a cosmetic defect.
For HPLC, GC, and LC-MS workflows, the practical question is not whether a fitted curve follows the visible trace. It is whether the model separates analyte signal from baseline and neighboring components well enough that the resulting peak parameters can withstand scientific review. HVL fitting is valuable because it addresses a common failure of simple symmetric models: real chromatographic bands often exhibit a structured leading or trailing distortion that changes quantitative results.
What the Haarhoff-van der Linde (HVL) Function Represents
The Haarhoff-van der Linde function is a chromatographic peak model designed to accommodate asymmetric band shapes. It extends beyond a standard Gaussian representation by incorporating a shape term that allows the peak to exhibit fronting or tailing behavior. In the symmetric limiting case, its behavior approaches that of a conventional Gaussian peak; as asymmetry increases, the model can describe the unequal rise and decay observed in actual separations.
This distinction is consequential. A Gaussian fit assumes that dispersion is distributed symmetrically about the peak center. Many instrument-generated chromatograms do not meet that assumption. Column interactions, sample overload, injection effects, extra-column volume, adsorption phenomena, detector response, and incomplete separation can all produce asymmetric profiles. Fitting such data with a symmetric function can force the optimizer to compensate in unhelpful ways, often by shifting the center, broadening the width, or assigning part of one analyte to another.
HVL is therefore best understood as a candidate model for chromatography where the observed line shape carries evidence of asymmetric transport or interaction effects. It is not a substitute for method development or a universal answer for every peak. It is a more appropriate mathematical description when the data demonstrate reproducible, non-Gaussian asymmetry.
Why Asymmetric Peak Models Matter for Quantitation
For an isolated, high signal-to-noise peak, several functions may generate a visually convincing overlay. The differences become much more apparent in difficult data: partially resolved components, trace-level analytes beside dominant peaks, broad peaks on drifting backgrounds, and sequences requiring consistent batch processing.
Peak area is particularly sensitive to model choice. If a tailing peak is forced into a Gaussian shape, the fit may underrepresent the extended tail or absorb it into a baseline term. If a fronting peak is treated as symmetric, the model may distort width and position to reduce residual error. In either case, the plotted fit can appear reasonable while the integrated area is not scientifically reliable.
The same concern applies to retention time and width-based performance metrics. A fitted center parameter is only meaningful in the context of the selected line-shape model. When the model does not represent the data-generating behavior, parameter values can become fitting artifacts rather than defensible analytical measurements.
This is why residuals matter. A low aggregate error alone does not establish that an HVL model is justified, nor does a smooth curve. Scientists should inspect whether residual structure remains around the apex, leading edge, and tail; whether parameter estimates are stable; and whether the function improves the model in a meaningful way relative to simpler alternatives.
When HVL Fitting Is a Strong Candidate
HVL fitting is most useful when chromatographic asymmetry is repeatable and materially affects the result. A recurring tail on a known analyte, for example, may be modeled more credibly with an asymmetric function than with multiple artificial Gaussian components. Likewise, an overlapping pair in which one component has a pronounced tail may require asymmetric component shapes to avoid biased area allocation.
It is especially valuable in four situations:
- Quantitative workflows where peak area or component fraction must be reported with traceable assumptions.
- Resolution studies in which neighboring peaks overlap enough that integration boundaries are not defensible.
- Method-development investigations where changes in peak shape may indicate overload, secondary interactions, or changes in column condition.
- Automated or high-throughput processing where a consistent model must be applied across many chromatograms rather than manually adjusted peak by peak.
That said, a complex function should not be selected merely because it has more flexibility. If the asymmetry is weak, inconsistent, or indistinguishable from noise and baseline error, a Gaussian or another simpler function may be preferable. Additional parameters can reduce residuals while increasing uncertainty, parameter correlation, and the risk of fitting noise. The appropriate model is the simplest one that captures scientifically meaningful structure.
HVL Peak Fitting Requires Baseline Modeling
A peak model cannot compensate for a poorly specified baseline. In chromatography, baseline drift, step changes, broad unresolved humps, solvent effects, and detector instability are frequently mistaken for peak asymmetry. This can lead an asymmetric peak function to absorb baseline curvature, producing a mathematically optimized but chemically misleading result.
The correct workflow models baseline and peaks together. Baseline regions should be selected with care, and the baseline form should match the local data behavior without becoming so flexible that it removes real analyte signal. For a narrow peak on a stable local baseline, a simple baseline may be sufficient. For a broad region with gradual curvature or unresolved background, a more structured baseline model may be required.
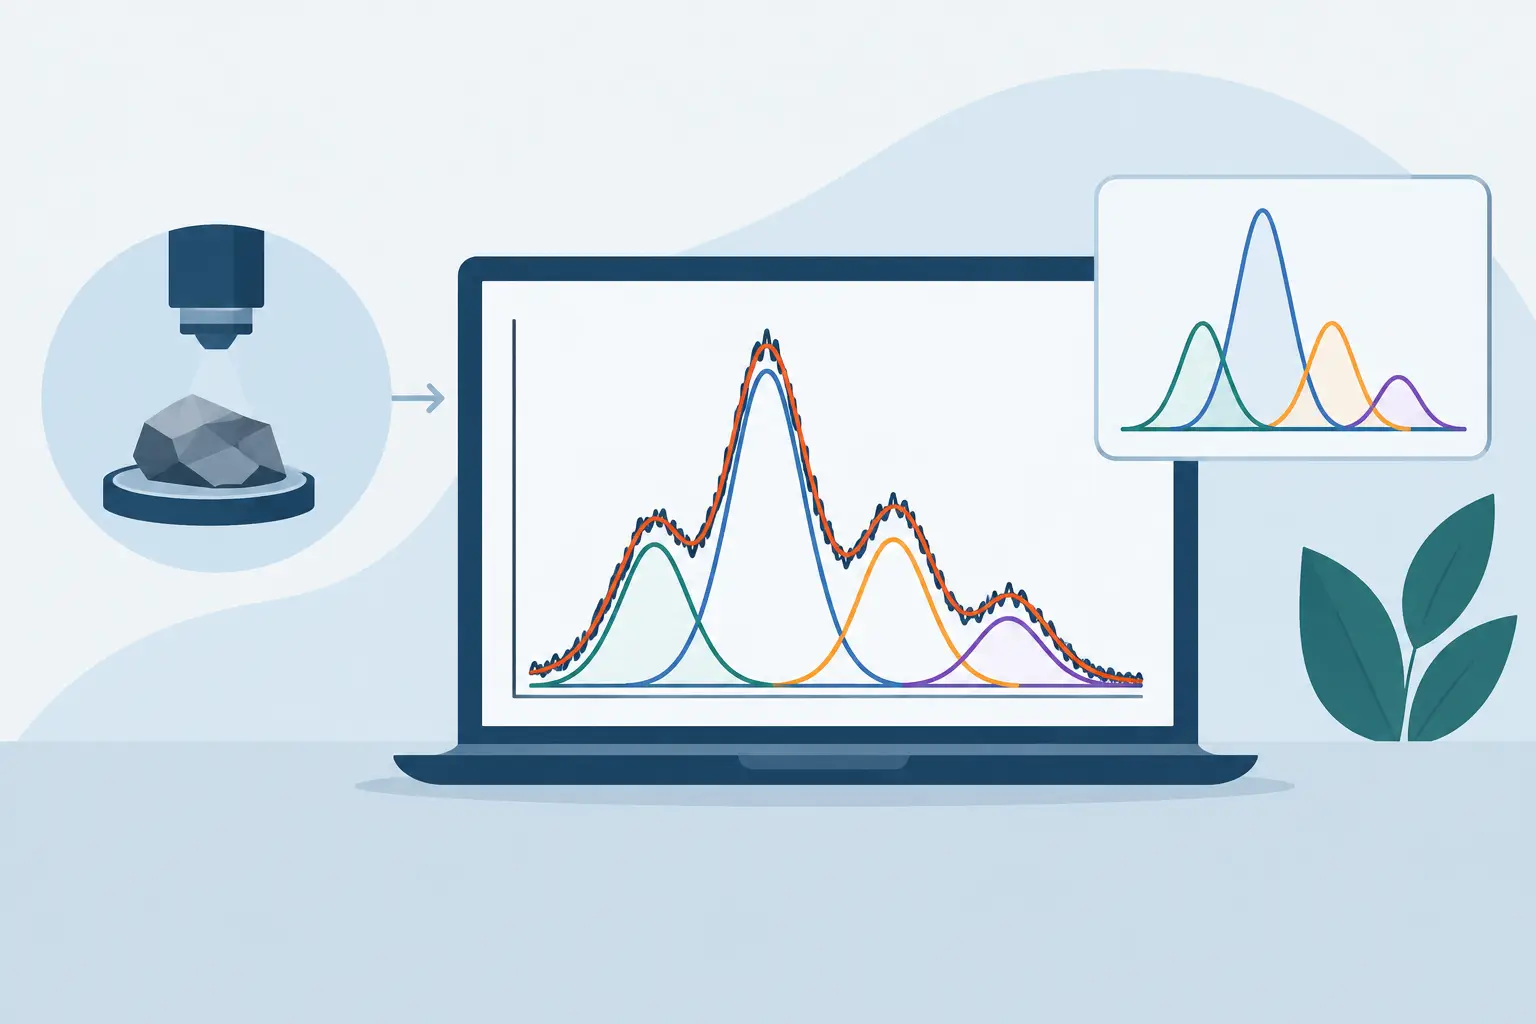
Joint optimization is critical for overlapping peaks. Sequential workflows that first subtract a baseline and then fit peaks can propagate baseline errors directly into component areas. Simultaneous baseline-and-peak fitting evaluates these contributions as one model, allowing the optimization to identify a statistically consistent allocation of signal.
Interpreting HVL Parameters Without Overclaiming
An HVL fit generally produces parameters associated with signal magnitude, location, peak breadth, and asymmetry. Those values should be interpreted as model parameters, not automatically as direct physical constants. Their usefulness depends on calibration, repeatability, data quality, and whether the selected function adequately describes the separation.
For routine quantitation, area and fitted location may be the primary outputs. For method development, the asymmetry-related parameter can be useful for tracking changes across columns, mobile-phase conditions, sample loads, or instrument maintenance intervals. A systematic increase in asymmetry can be meaningful, but only if the acquisition conditions and fitting protocol are controlled.
Parameter correlation deserves particular attention. In partially resolved peaks, amplitude, width, position, and asymmetry can influence one another. An optimizer may find multiple parameter combinations with similar residual errors. Constraints based on known retention windows, positive amplitudes, expected widths, or shared shape behavior can reduce nonphysical solutions. Constraints must be scientifically justified, documented, and applied consistently, not used to force a preferred result.
A Defensible Workflow for Haarhoff-van der Linde (HVL) Analysis
Start with the raw chromatogram at sufficient sampling density. Avoid aggressive smoothing before fitting, since smoothing can alter peak widths, suppress shoulders, and create false confidence in a chosen line shape. Establish the fitting interval wide enough to include the full asymmetric tail or front, along with baseline regions on both sides whenever the data permit.
Next, compare plausible models rather than assuming HVL is correct. For an isolated peak, compare a Gaussian fit with an asymmetric alternative and examine the residual pattern, parameter uncertainty, and relevance of the improvement. For unresolved components, test whether HVL reduces systematic residuals and produces stable component areas across replicate injections. Visual inspection remains necessary, but it should be paired with quantitative diagnostics.
Then apply analytical constraints where the chemistry supports them. A known number of components, positive concentrations, plausible retention ordering, and reasonable width ranges can prevent an optimizer from creating implausible solutions. Do not constrain asymmetry simply to make peaks look consistent unless there is independent evidence for that assumption.
Finally, retain the fitting record: raw data, baseline model, fitting range, component functions, initial conditions or automated detection settings, constraints, convergence status, residual statistics, and final parameter estimates. This is what turns a fitted chromatogram into a reproducible analytical result.
Professional peak-fitting environments such as PeakLab can support this workflow by combining asymmetric peak functions, baseline correction, automatic peak detection, constrained nonlinear optimization, and statistical reporting in one analysis process. The goal is not to generate a more attractive trace. It is to produce component models that can be evaluated, reproduced, and defended.
Choosing HVL Against Other Peak Shapes
HVL should be compared with alternatives according to the data and the analytical purpose. Gaussian functions remain useful for symmetric, well-resolved peaks because they are parsimonious and easy to interpret. Exponentially modified Gaussian and related functions may be effective when a one-sided tailing mechanism is evident. Lognormal-type functions can also describe asymmetric signals in some datasets.
The deciding factor is not a function’s reputation or its ability to minimize error on one chromatogram. It is whether the model captures recurring peak behavior across relevant samples and produces reliable quantitative outputs. A model that fits one injection exceptionally well but gives unstable areas across replicates is less useful than a slightly simpler model with consistent, interpretable parameters.
Treat the Haarhoff-van der Linde function as an analytical hypothesis: test it against the residuals, the chemistry, replicate behavior, and the decisions the data must support. When those lines of evidence agree, HVL fitting can convert asymmetric chromatographic profiles from a source of integration error into defensible quantitative information.