A Guide to Uncertainty Propagation Analysis
A fitted peak area reported as 12,438 counts can look precise while carrying an uncertainty large enough to change a release decision, a concentration estimate, or a mechanistic interpretation. This guide to uncertainty propagation analysis addresses the required next step after fitting: determining how uncertainty in measured signals, baseline terms, and fitted parameters affects the final reported result.
For analytical scientists, uncertainty propagation is not a decorative error bar added after the model is complete. It is the statistical connection between the instrument response, the assumptions embedded in the model, and the quantity used to make a scientific claim. If that connection is incomplete, a visually convincing fit can still produce a result that is difficult to defend.
What uncertainty propagation analysis measures
Uncertainty propagation estimates the uncertainty of a calculated output from the uncertainty of its inputs. In a simple calibration calculation, the output may be concentration. In peak fitting, it may be peak area, centroid, full width at half maximum, relative abundance, resolution, or a ratio between components. In surface fitting or kinetic modeling, it may be an interpolated value, a rate constant, or an optimized operating condition.
The central question is direct: if the inputs vary within their known or estimated uncertainty, how much can the reported result vary?
Consider a derived quantity, (y=f(x_1,x_2,…,x_n)). The inputs may include observed intensities, calibration coefficients, peak-shape parameters, baseline coefficients, dilution factors, and detector-response corrections. Each input has uncertainty, and some inputs are correlated. Propagation analysis translates that joint uncertainty into an uncertainty for (y).
This distinction matters because standard deviation, standard error, confidence interval, and prediction interval answer different questions. A parameter standard error describes estimated sampling variability under a model. A confidence interval describes plausible values for an unknown parameter at a stated confidence level. A prediction interval also includes the variability expected in a future observation. Reporting one in place of another can materially overstate precision.
Start with a model that represents the measurement
Propagation cannot repair a model that is chemically or physically inadequate. A fitted curve may have low residual error because flexible terms absorbed baseline drift, unresolved overlap, detector artifacts, or an incorrect peak shape. The resulting covariance matrix can appear favorable while the reported peak area remains biased.
For chromatographic or spectroscopic data, begin by defining the measurement model explicitly. Specify the baseline function, peak family, constraints, shared parameters, integration limits, calibration function, and any corrections applied after fitting. The final measurand must be equally explicit. “Peak area” is not always sufficient. Is it the area of the analytic peak only, the area after baseline subtraction, the sum of two constrained components, or an area normalized to an internal standard?
The uncertainty budget should follow that definition. A peak height calculation may be sensitive to sampling interval and noise near the apex. An integrated area may be more sensitive to baseline placement and overlap. A concentration derived from an external calibration also depends on the uncertainty of slope, intercept, reference preparation, dilution, and replicate response.
Random error and systematic effects are not interchangeable
Random effects include detector noise, injection-to-injection variation, and finite sampling. They are often characterized with replicate measurements or residual analysis. Systematic effects include calibration bias, wavelength error, baseline model inadequacy, incorrect response factors, and unrecognized coelution. They do not disappear simply because more points are added to a fit.
A complete uncertainty statement should distinguish the two. Replicate precision alone is not total uncertainty. Conversely, adding a broad estimated systematic term without identifying its source does not establish traceability. The useful approach is to document each credible source, determine whether it is random or systematic, and quantify it using calibration data, validation experiments, reference materials, method studies, or scientifically justified bounds.
The first-order method and the role of covariance
For differentiable models with relatively small uncertainties, first-order propagation is often appropriate. The approximate variance of an output is:
[ u^2(y) approx JSigma J^T ]
Here, (J) is the Jacobian, containing the partial derivatives of the output with respect to every input, and (Sigma) is the covariance matrix of those inputs. The square root of (u^2(y)) is the combined standard uncertainty.
The covariance matrix is essential in nonlinear fitting. Parameters in overlapping peaks are commonly correlated: amplitude may trade against width, centroid may shift with asymmetry, and baseline coefficients may trade against broad peak area. Treating every fitted parameter as independent usually understates uncertainty because it removes these coupled changes from the calculation.
For example, two partially resolved Gaussian components may return stable total area but unstable individual areas. Their amplitudes can be strongly anticorrelated. If the analytical question concerns total analyte response, propagation through the summed area may produce an acceptably narrow interval. If it concerns the ratio of the two components, the propagated uncertainty may be large. Neither result is an error. They describe different measurands supported by the same data.
First-order methods are efficient and interpretable, but they depend on local linearity. They can become unreliable when parameter uncertainty is large, constraints are active, the output is a nonlinear ratio, or the parameter distribution is asymmetric.
When Monte Carlo propagation is the better choice
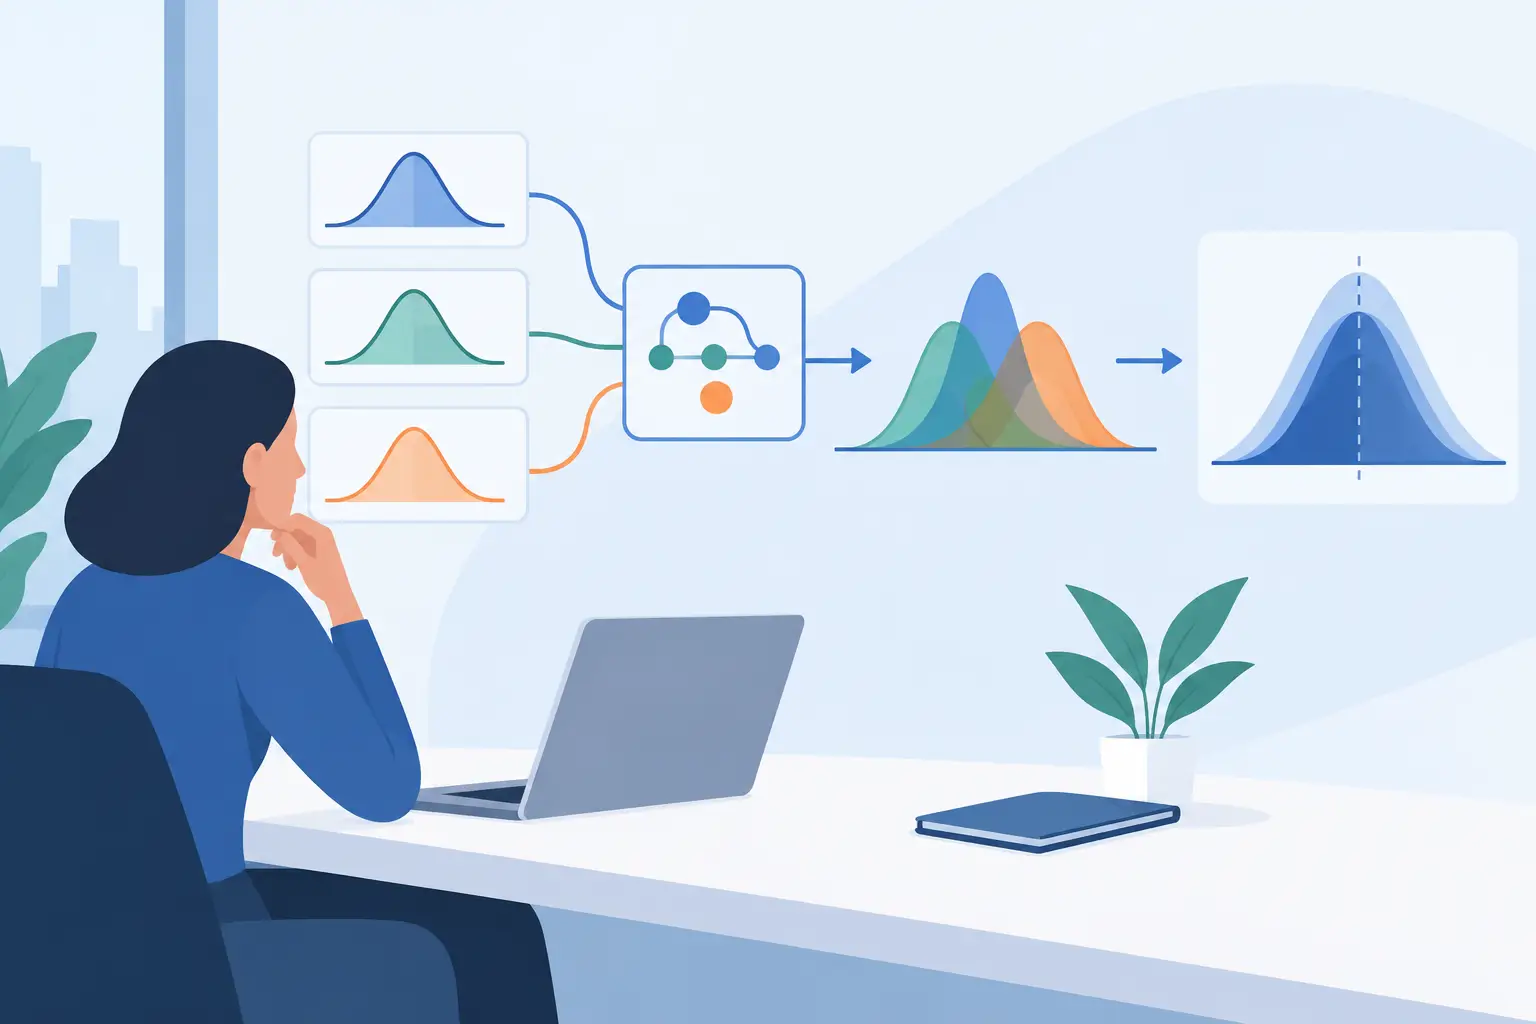
Monte Carlo propagation evaluates the full calculation repeatedly using sampled input values drawn from their assigned uncertainty distributions. The resulting distribution of outputs provides an empirical estimate of uncertainty, confidence bounds, skewness, and the probability of exceeding a decision threshold.
This approach is especially valuable for low signal-to-noise peaks, severe overlap, nonlinear calibrations, bounded parameters, and derived quantities such as ratios or limits of detection. It is also useful when a fitted parameter cannot be assumed normally distributed. A width constrained to remain positive, for instance, may have a distinctly asymmetric uncertainty distribution near the constraint boundary.
The method is only as credible as its inputs. Sampling fitted parameters independently when they are correlated defeats a major advantage of Monte Carlo analysis. Use the joint parameter covariance structure where the approximation is valid, or refit simulated datasets when model nonlinearity and constraints are dominant. Refit-based simulation is more computationally demanding, but it more faithfully captures the actual fitting workflow.
A practical workflow for fitted analytical data
A defensible workflow begins before the final fit. First, define the reported quantity and its decision use. A screening result, a publication value, and a regulated release specification may require different uncertainty coverage and documentation.
Next, fit the signal using a justified baseline and peak model. Examine residuals rather than relying on visual agreement alone. Structured residuals, unexplained shoulders, or concentration-dependent peak-shape changes indicate that the model may not support valid propagation.
Then obtain parameter estimates and their covariance information from the nonlinear regression. Include uncertainty from calibration and sample preparation where those steps contribute to the final value. If the output is a peak area converted to concentration, the fitting uncertainty is only one component of the calculation chain.
Select the propagation method based on the behavior of the model. First-order propagation is appropriate for well-behaved, locally linear calculations with modest uncertainty. Use Monte Carlo or simulated-data refitting when the output is nonlinear, constrained, asymmetric, or near a reporting threshold.
Finally, report the result with its basis. State the measurand, uncertainty value, coverage factor or confidence level, method of propagation, relevant model assumptions, and treatment of covariance. A statement such as “concentration = 4.26 ± 0.18 mg/L, 95% confidence interval, including fit, calibration, and dilution uncertainty” is materially more useful than an isolated decimal value.
Common failure modes in uncertainty propagation analysis
The most frequent error is propagating only the standard errors of fitted peak parameters while ignoring baseline and calibration uncertainty. This can be acceptable only when validation demonstrates that those omitted terms are negligible for the stated measurand.
Another failure is using the residual standard deviation as a universal uncertainty estimate. Residual scatter reflects model-data mismatch under a particular fit. It does not automatically describe uncertainty in each parameter or in every derived result. Parameter sensitivity and covariance determine how residual noise reaches the output.
Analysts also sometimes use a confidence interval from an unconstrained fit after applying constraints in the production workflow. Constraints alter the parameter space and can change the uncertainty distribution substantially. The reported uncertainty method must reflect the model actually used.
A final concern is model selection. Choosing the peak count, baseline order, or peak family from the same dataset introduces selection uncertainty. Where alternative models are scientifically plausible and yield materially different results, that spread should be investigated rather than hidden. The appropriate response may be additional experimental resolution, a better constrained model based on known chemistry, or an uncertainty component representing model ambiguity.
Build uncertainty into the analytical workflow
Scientific fitting software should preserve more than optimized parameter values. It should retain the data treatment, baseline model, peak definitions, constraints, residual diagnostics, covariance information, and statistical reporting required to reconstruct the result. In workflows involving repeated samples or batch data, consistent model definitions are equally important because manual adjustments can create untracked variation.
A specialized environment such as PeakLab can support this discipline by integrating baseline-and-peak modeling with nonlinear fitting and statistical outputs, rather than treating fitting and uncertainty reporting as separate tasks. The analyst must still define the correct measurand and validate the model, but the workflow becomes more traceable when those decisions are captured with the fit.
The most useful uncertainty analysis is the one that changes how confidently a laboratory can act. When a result sits near a specification limit, a detection threshold, or a scientific cutoff, revisit the signal model and the uncertainty budget before reporting another decimal place. That is where propagation analysis turns a fitted curve into evidence that can withstand review.